Measured harness ledgerPublic result
GPT-6.1 SolBlossom arena — GPT-6.1 Sol
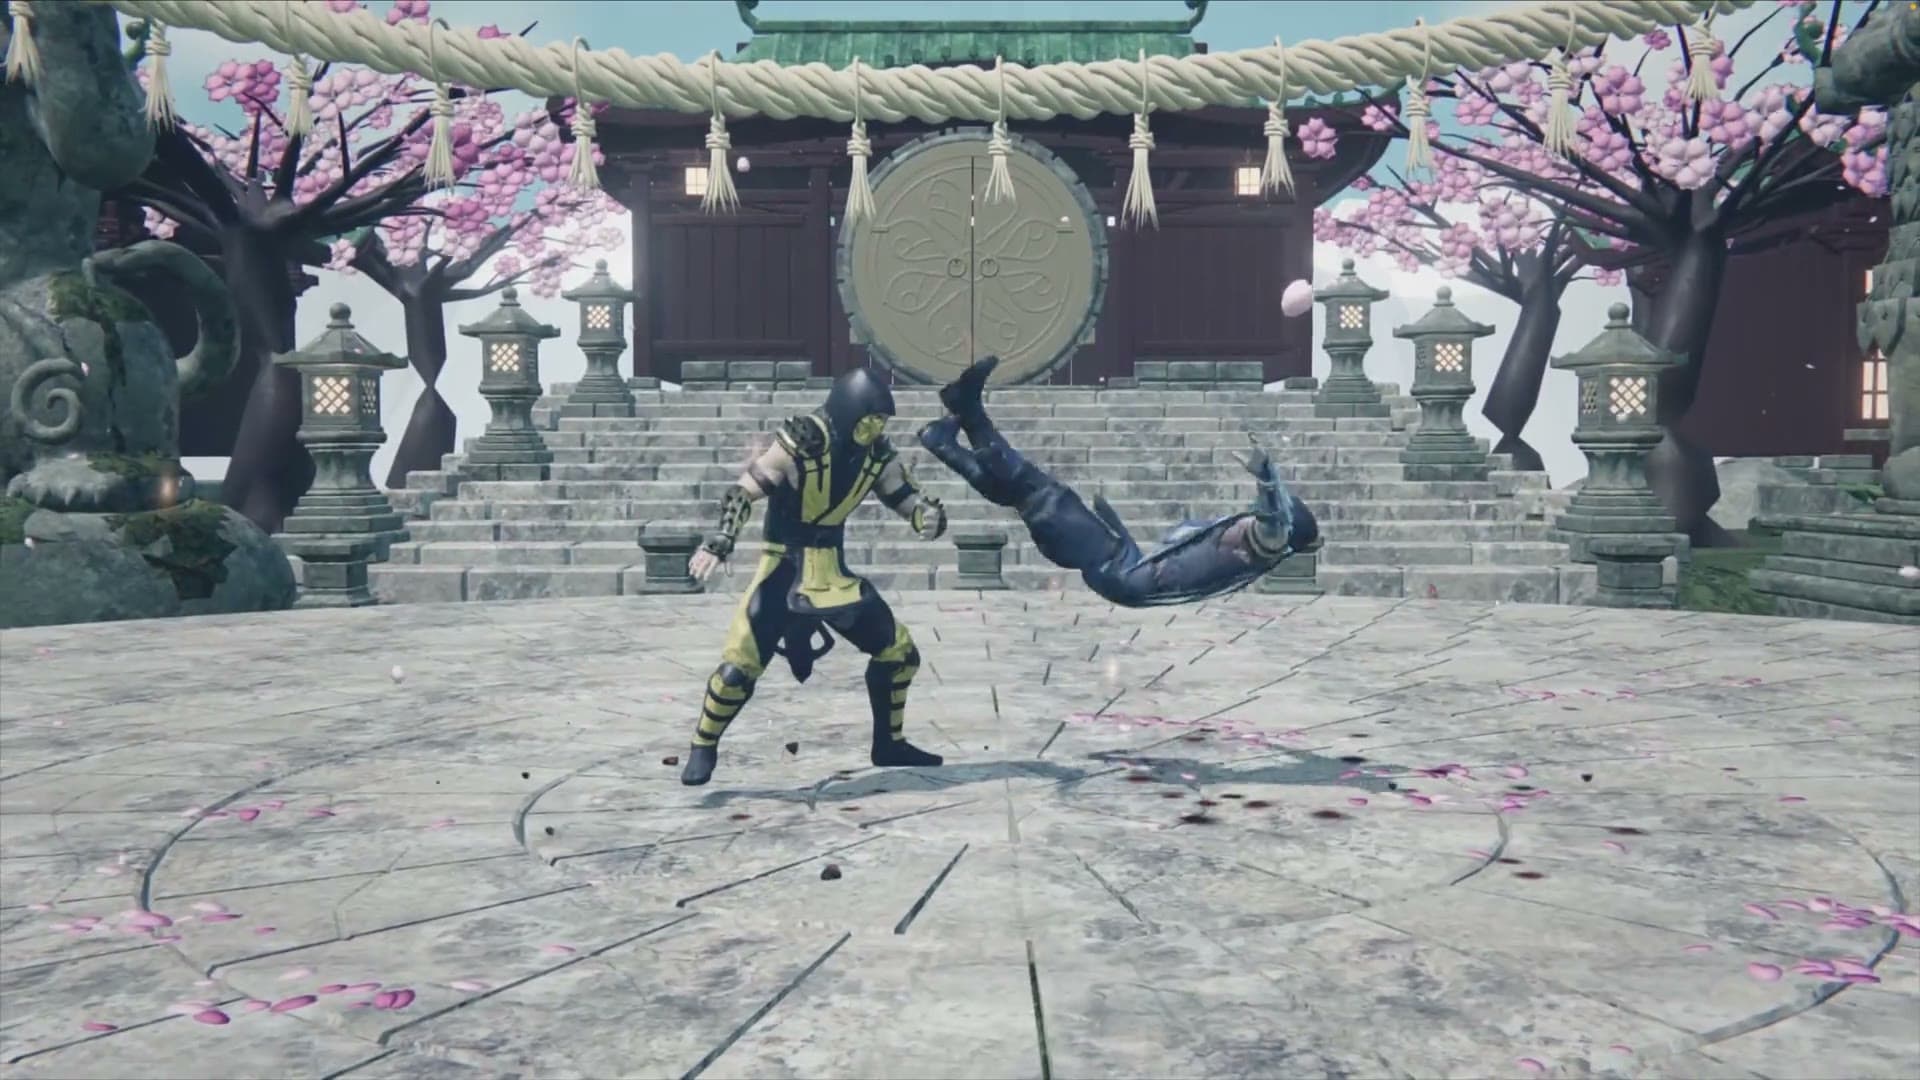
Build the cherry-blossom temple courtyard arena in Blender through the pinned reference-exposed task.
Max reasoningHeadline result
- Workflow cost
- $21.16
- Wall-clock
- 3h 47m 09s
- Processed tokens
- Total input 79,235,643 (fresh input 2,864,059 + cache read 76,371,584 + cache creation 0). Output generation 779,477 is not included in that input total. Reasoning subset 373,547 is inside output and is not added. No processed total is recorded.
- Record state
- additive_harness_projection
Public summary
GPT-6.1 Sol Blossom arena: 3h 47m 09s, $21.16 API-equivalent estimate, Total input 79,235,643 (fresh input 2,864,059 + cache read 76,371,584 + cache creation 0). Output generation 779,477 is not included in that input total. Reasoning subset 373,547 is inside output and is not added. No processed total is recorded..
Run identity and stack
- Result ID: courtyard-arena-blossom-stage-2-reference-exposed-gpt-6.1-sol-max-20261001
- Technical model: gpt-6.1-sol
- Provider: OpenAI Codex
- Client: Codex CLI
- Stack: Blender MCP
- Stack: Courtyard blossom stage 2
Cost basis
- Clock is measurements.model_invocation_wall_seconds. The root receipt status is stopped_by_user. Cost is api_cost.total_usd. Actual subscription charge is null.
- Source: measurements.token_usage.total_input at harness commit 9b7c614dbb5103cc373fdf6275b5c4efc10d8f0e.
Validation evidence
- Result: STOPPED_PARTIAL
- Verification: Recorded status is partial_user_stopped. Pending, partial, stopped, qualified, and model-finished states stay unjudged. Additive projection from harness commit 9b7c614dbb5103cc373fdf6275b5c4efc10d8f0e. Broad harness sync was not run. Clock is measurements.model_invocation_wall_seconds. The root receipt status is stopped_by_user. Cost is api_cost.total_usd. Actual subscription charge is null. Source: measurements.token_usage.total_input at harness commit 9b7c614dbb5103cc373fdf6275b5c4efc10d8f0e.
Recorded caveats
- Status partial_user_stopped and verdict STOPPED_PARTIAL. The episode says the GPT models finished. That narration does not change this status.
- Clock is measurements.model_invocation_wall_seconds. The root receipt status is stopped_by_user. Cost is api_cost.total_usd. Actual subscription charge is null.
- Source: measurements.token_usage.total_input at harness commit 9b7c614dbb5103cc373fdf6275b5c4efc10d8f0e.
Visible evidence gaps
- additive projection; broad harness sync was not run
- source harness commit 9b7c614dbb5103cc373fdf6275b5c4efc10d8f0e
Public result only
This result keeps its public summary and evidence, but it does not currently have a matching Builder test with prompts, projects, Harness workflows or skills.